Website file backups versus database backups: check recovery scope before rollback
"The website is backed up" needs a further question: which objects and recoverable states? Programs, article data, and uploaded images may occupy different locations. Restoring one does not automatically restore others.
Actual storage defines recovery scope. This article mainly addresses CMS sites separating code and content databases; static and hosted platforms may differ. Locate real objects before discussing restoration rather than infer whole-site coverage from archive names.
Locate programs, content, assets, and settings
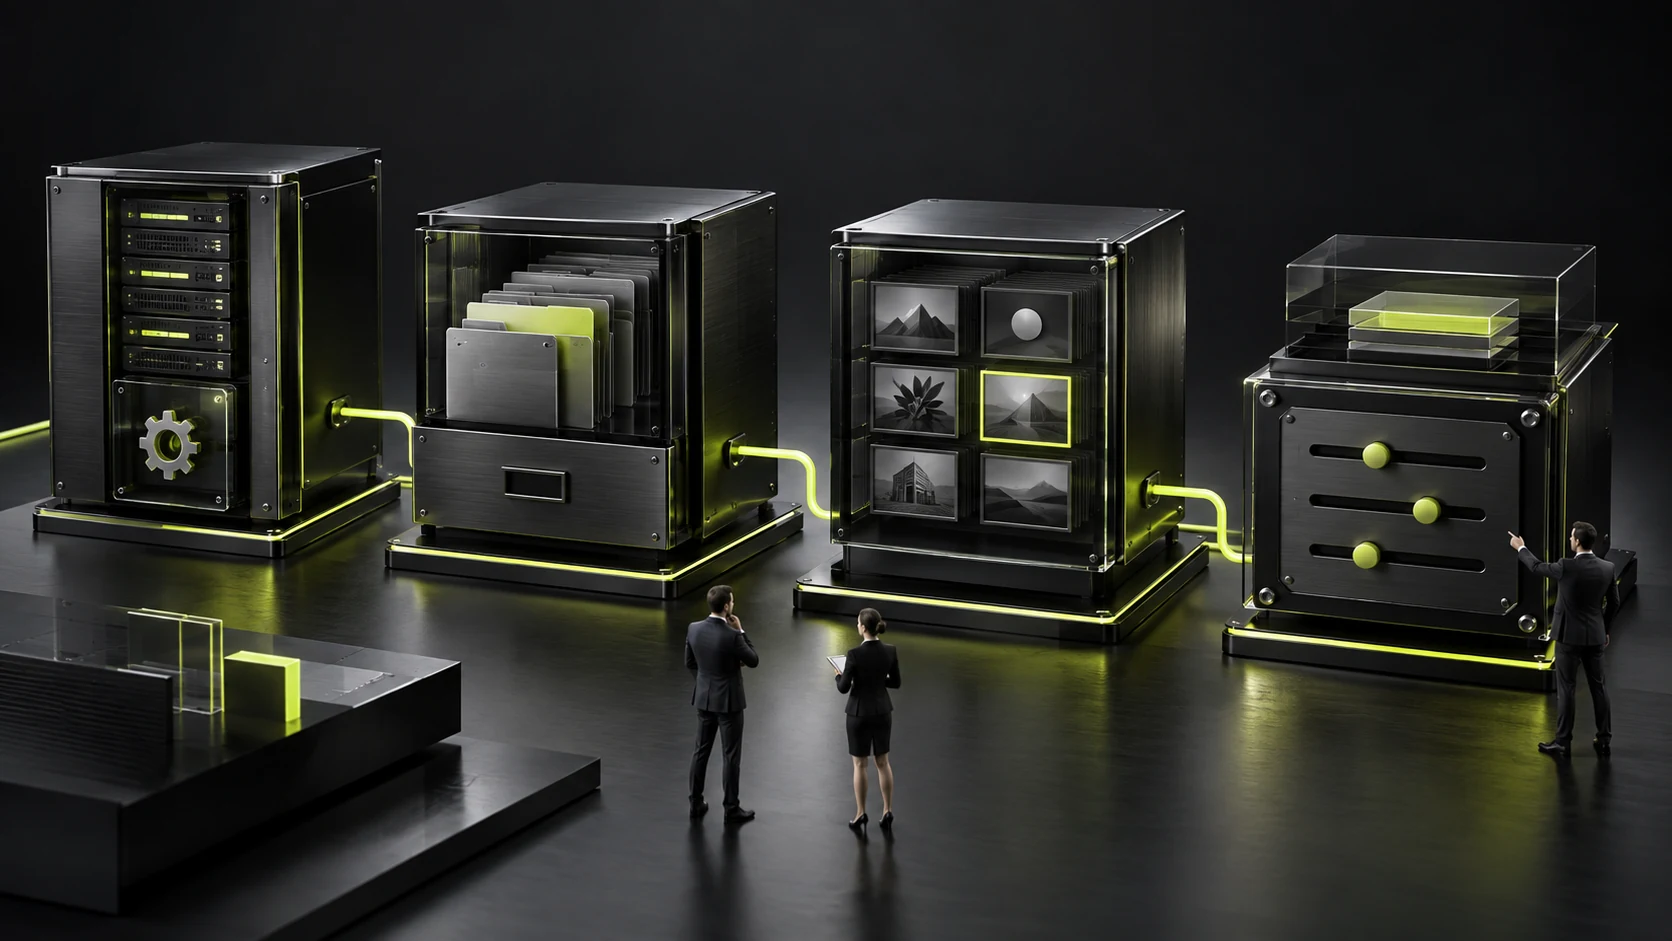
Code controls pages and administration, databases may hold articles, categories, publication states, and form records, uploads hold images and files, and settings control connections and business rules. Sites may combine these or distribute them among services.
Ask implementers for a minimal inventory of objects, locations, backup methods, time, owners, and recovery evidence. Staff need not know every directory but should identify backups for articles, inquiries, and images.
For database articles and uploaded illustrations, downloading code alone is not complete content backup. Conversely, exported article data without images may restore text with broken pictures.
Separate configuration locations too: database, environment, or files. Restored code reading current configuration may keep new notification addresses; old configuration files may reverse settings unintentionally.
Include external assets: independent image storage, third-party forms, and actual emails outside site databases. Program backups cannot restore these automatically. List separate exports and retention by architecture.
Keep necessary identities without public secrets. Manage credentials through controlled access and document ownership and retrieval. Putting every password in instructions does not improve recoverability. See Website Project Handoff Checklist for related checks.
File backup does not automatically include databases
"File backup" may mean copied code and assets or a complete cloud snapshot, with differing scope. Check actual database, external storage, and service inclusion rather than trust "Full."
Logical exports and physical database copies have different processes and restoration requirements. Maintainers should use verified system-appropriate methods and instructions; operators need not guess commands.
Databases use files, but ordinary web-directory archives are not automatically valid database backups. Consistency and recovery requirements matter; incorrect copying may yield files unable to restore completely. See How to Back Up a Corporate Website and Test Recovery for related checks.
Check times too. Morning code, afternoon data, and yesterday's uploads may not form one usable state. Changes between backups require explicit missing-object and relationship handling.
Full and incremental scope needs clarity. Changes since earlier backups may depend on a baseline. Record dependencies and order instead of expecting maintainers to guess completeness from sizes.
Backup task success does not prove restore usability. Verify reading and relationships in isolation before treating backups as recovery evidence. Archive existence or normal sizes cannot establish business takeover.
Why articles may remain published after program restoration
Where text and publication states live in databases, publishing changes data. Restoring button code does not return articles to drafts. Different object scope is not necessarily failed recovery.
After adding bulk publishing and publishing drafts, restoring old interfaces and controllers may remove buttons while articles stay public. Interface recovery and content withdrawal differ.
JVDS Design Studio's confirmed bulk-publishing work includes Chinese-English synchronization and remaining-draft checks. It shows why states need actual inspection; this article claims no rollback incident or particular recovery result on the site.
Restoring an entire old database is also more than undoing publication. Later inquiries, edits, and other data may be affected. For withdrawing a batch, define its list and current states rather than blindly reverse everything.
Uploads are another layer. Restored old image URLs without corresponding files can leave pages incomplete. Check states, text, and references separately within scope.
Agree goals and permitted losses before restoring
Goals may be running earlier code, restoring one article, withdrawing a batch, or returning a whole site to a confirmed state. Each needs different objects and actions. Vague "Restore normal" permits conflicting expectations.
State current problems and expected results, then objects restored and preserved: earlier code with new inquiries retained, or changed publication states with unchanged text. Implementers can choose appropriate paths.
Ongoing editing and form writes need pauses, tracking, or merging in affected scope. Otherwise new changes may enter no checking list. Business and implementation staff should agree limits rather than overwrite growing data for convenience.
Back up current state too. Old backups do not represent the present; unsuitable recovery must permit return to the pre-operation state. Maintainers determine methods and pauses for the system.
Specify target times, backup dates, environments, and versions, beyond "Yesterday." Test and production archives sharing names cannot mix. Confirm data and assets belong to the same site.
Code may depend on database schemas. Old code over new structures or old data losing new fields can create issues. Verify compatibility in isolation before production restoration rather than guess live.
Use independent checks to establish correct recovery scope
Inspect target outcomes beyond the homepage. Code recovery needs affected administration and features; withdrawals need article states and public access; material recovery needs retrievable files and images.
Read actual saved content before public pages, accounting for cached states. Unchanged appearance needs comparison of records and references rather than repeated database restoration. Assess display and storage separately.
An independent checker can follow the goal list. Executors may equate completed actions with correct results, while another person checking records and pages may catch missing objects. Keep checks proportional to changes.
Check business records separately against preservation lists: new inquiries, contacts, and descriptions. Working pages do not prove dynamic data survived.
Inspect actual multilingual relationships. Withdrawn Chinese with published English may violate goals; restored text with lost relationships also needs handling. Match scope to the operation without aimless historical checks.
Success means agreed objects meet explicit goals, retained current data stays complete, assets remain associated, and functions work. Document restored scope, excluded scope, and issues so uploaded files are not mistaken for complete historical recovery.
Frequently asked questions
Can one source-code archive restore a whole website?
Only with required objects and verified restoration. Dynamic CMS sites usually also need databases, uploads, and settings. Check platform and snapshot coverage too.
Why not simply copy databases if they are files?
Consistency and restoration have specific requirements. Ordinary directory copying is not automatically valid. Use supported methods maintainers can verify.
Does restoring code return articles to draft automatically?
Usually not when states live in databases. Handle actual saved objects rather than treat interface restoration as content withdrawal.
Should withdrawing a few articles restore the entire old database?
Not without scope checks. Other new data may exist since backup. List changed content and preserved records before implementation planning.
How can backup usability be proven?
Restore agreed objects in isolation and check records, assets, and key functions. Task success, file existence, or an open homepage cannot independently prove complete recovery.
 Link copied