
Many sites Disallow a page in robots.txt to keep it out of Google. Search engines then cannot read its noindex, and external links may still surface the URL without a snippet.
The tools solve different problems: robots.txt manages crawling; noindex directs indexing. Sensitive content requires authentication and permissions, not either tool.
01 robots.txt Controls Crawler Access
It can reduce crawling of admin areas, internal search, infinite parameters, or low-value resources, but its rules are public and do not stop every robot.
Disallowed URLs may still be discovered through external links; search engines simply cannot read their content or meta directives.
02 noindex Requires a Crawlable, Readable Page
Set noindex in HTML meta robots or an HTTP header; after crawling, search engines exclude the page from the index.
Blocking the same page in robots.txt can hide noindex. Usually allow crawling until noindex is processed, then consider crawl restrictions.
Recommended Treatment by Page Type
| Page Type | Recommended Method | Explanation |
|---|---|---|
| Login and Account Pages | noindex plus real access control | Never rely on robots for privacy |
| Staging or Preproduction | Authentication or IP restriction | Safer than public noindex |
| Internal Search Results | Usually noindex; manage crawling at scale | Prevent many thin pages from indexing |
| Filter Parameters | Choose canonical, noindex, or crawling by search value | No universal rule |
| PDFs and Other Non-HTML Files | X-Robots-Tag noindex | Meta tags do not apply |
| Sensitive Data | Authentication, authorization, and server security | Neither robots nor noindex is security |
03 Never Use robots.txt to Hide Secrets
Anyone can read the file, which exposes blocked paths. Admin tools, customer data, quote systems, and test APIs need authentication and authorization.
If content has leaked, remove it, revoke access, clear caches, and use search-removal tools where appropriate; one Disallow line is insufficient.
04 Manage Parameter Pages by Scale and Value
Commerce, directories, and content sites generate sorting, filtering, pagination, and tracking parameters. Some combinations have search value; most duplicate other views.
Define canonical URLs, internal links, and indexing first, then crawling. Excessive blocking can hide important products.
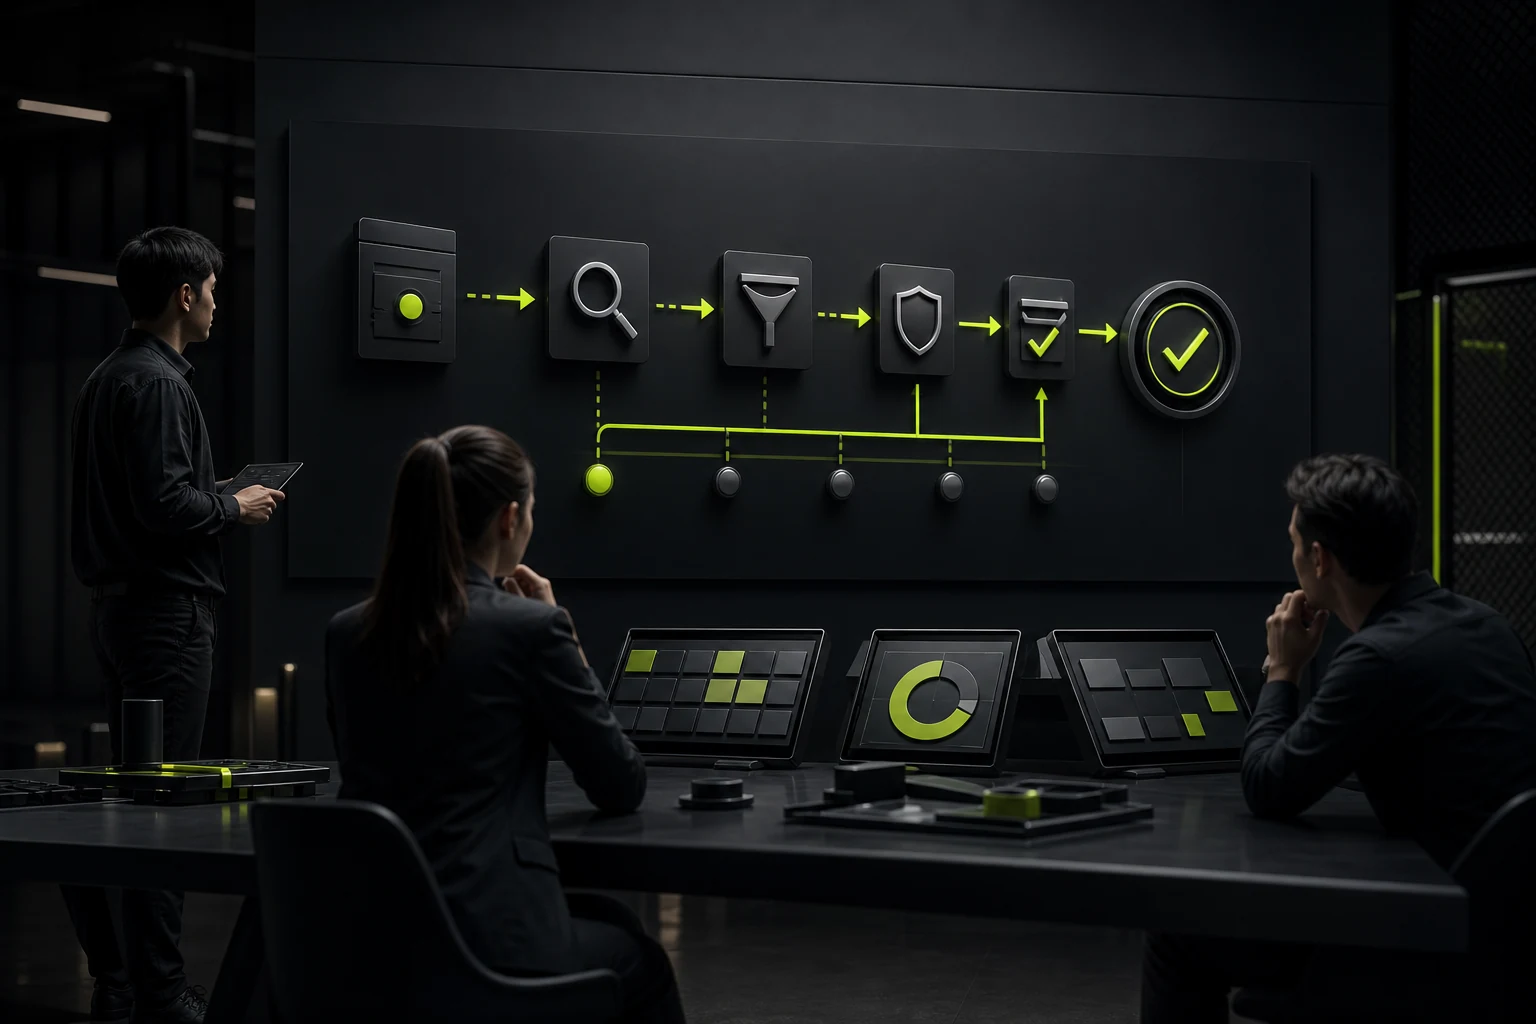
05 Prevent noindex from Leaking into Production
Staging often uses sitewide noindex. Forgetting to remove it at launch prevents indexing. Add release checks and production alerts.
If temporary pages index accidentally, verify whether canonicals, Sitemaps, and internal links continue sending inclusion signals.
06 Validate Real Results with URL Inspection
Check whether Google can crawl, which directive it detects, which canonical it selects, and how index status changes.
Do not inspect source alone. JavaScript injection, caches, CDNs, and HTTP headers can make production differ from local code.
Frequently Asked Questions
Can robots.txt Remove a Page from Google?
Not reliably. It blocks crawling, but the URL may still be discovered. Index removal generally requires crawlable noindex.
Can a noindex Page Appear in a Sitemap?
It should not. A Sitemap lists canonical URLs intended for indexing; noindex states the opposite.
Does a Login Page Need noindex?
Usually, but it also needs real authentication. noindex affects search visibility, not security.
What Is the Difference Between nofollow and noindex?
noindex controls indexing of the current page; nofollow addresses link following or signals.
Can a Page Be Disallowed After Leaving the Index?
Potentially, based on crawl budget, but first confirm the engine processed noindex and removed it.
| Service | View |
|---|---|
| Related Services | View Service Details |
| Project Inquiry | Contact JVDS Design Studio |
| Design and Website Development Articles | View Service Details |
 Link copied








