
What exactly is the difference between robots.txt and noindex? One tube for crawling and the other for indexing. Never use them in reverse
The Disallow in robots.txt tells crawlers "Do not crawl here", and the noindex tells searches "Do not index this page". Disallowing a page and adding "noindex" at the same time may seem like a double guarantee, but in fact, web crawlers may not be able to see the "noindex" at all.
01 First, understand Crawling and Indexing separately
Crawling is when search engines visit URLs to obtain content, while indexing is to determine whether the content has entered the search database. robots.txt mainly controls the crawling behavior, while noindex mainly controls the index.
These two stages are different, so one mechanism cannot replace the other.
02 Disallow does not guarantee that the URL will never appear in the search results
The current Google robots.txt document clearly states that the content of a disallowed page cannot be crawled, but the URL may still be indexed without a summary, such as when a large number of external pages link to it.
If the business goal is "This page should not appear in search", noindex or access control should be used instead of just writing robots.txt.
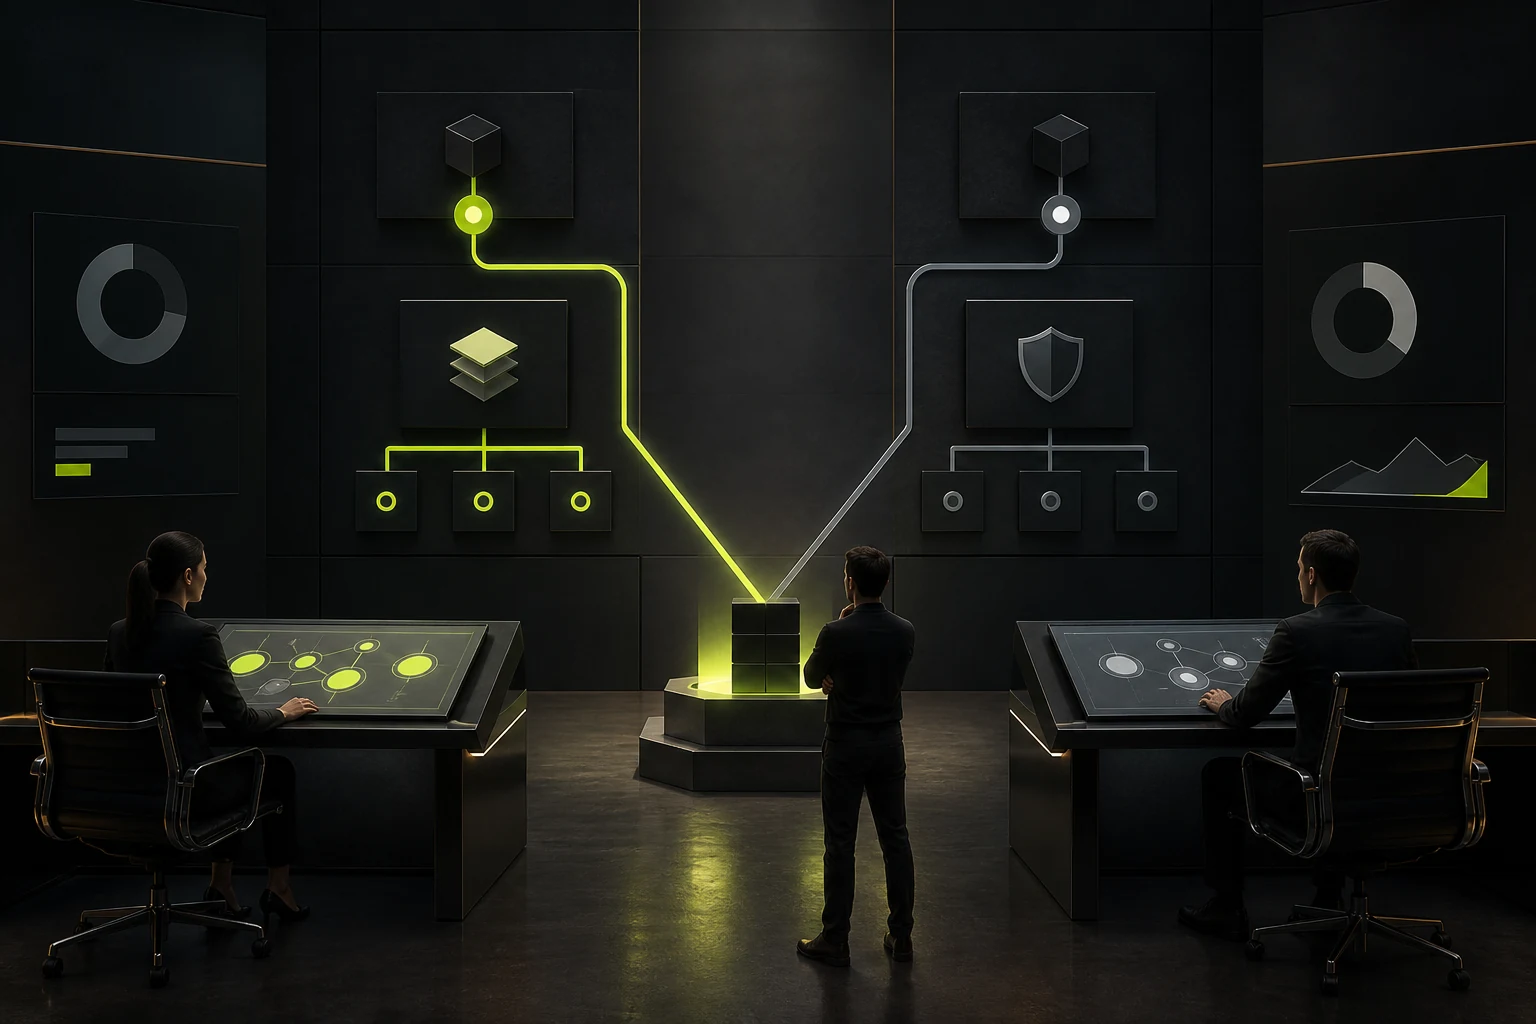
03 noindex must be visible to Google
After the page returns noindex through meta robots or HTTP Header, Google needs to crawl the page to read the instructions.
If the robots.txt file also blocks crawling, search engines may not be able to detect noindex, resulting in the common question "I clearly added noindex, so why is it still there?"
04 Logins, private and sensitive content should not be protected by robots.txt
robots.txt is a public file, and anyone can view the directories listed in it. It is not access control.
Data that should not be publicly accessed should be protected through security mechanisms such as login, permission, and network restrictions. SEO tags cannot replace information security.
05 The test environment should be blocked from the infrastructure layer instead of remembering noindex before going live
The most common incidents in Staging are that the test site is indexed by search or the noindex of the entire site is forgotten to be removed when going live. A more reliable approach is to use methods such as identity verification and IP restrictions.
If noindex is indeed used, "production environment removal" should also be added to the automated release check instead of relying on someone's memory.
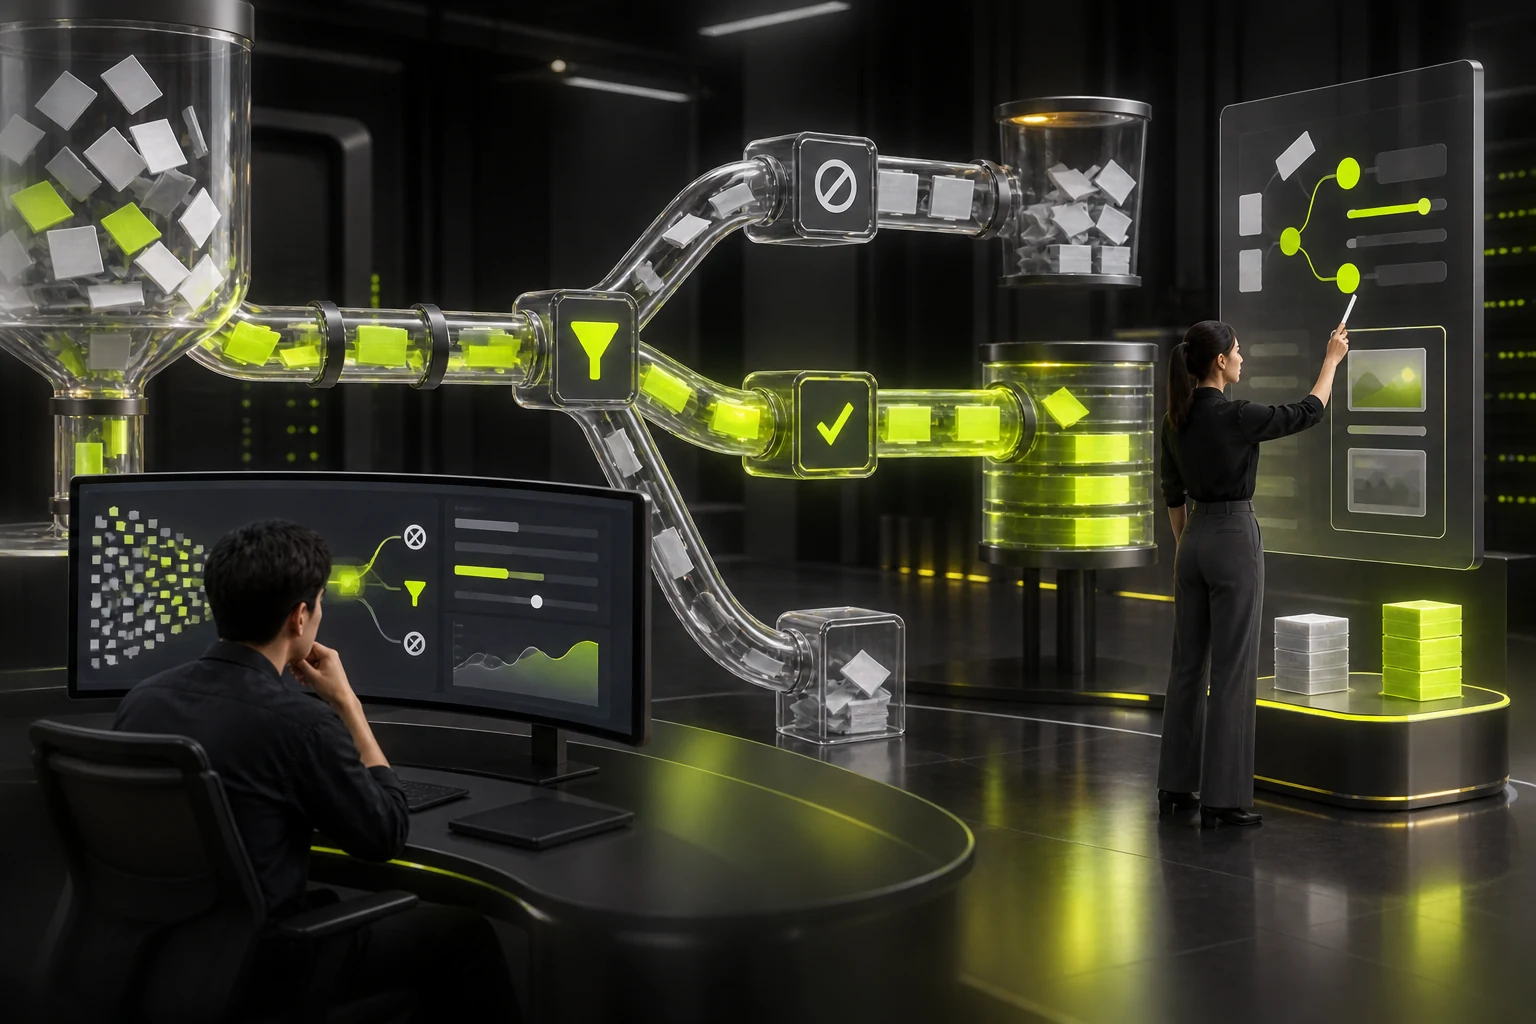
06 Do not Disallow all the filter and parameter URLs as soon as you see a large number
Whether the parameter page should be crawled and indexed depends on the page value. Completely prohibiting crawling may prevent search from seeing canonical, links, and content relationships.
It is necessary to first clarify which combinations have independent search value and which are only for sorting, tracking or user status, and then handle them separately.
07 The robots.txt rule has a scope. Subdomains and protocols cannot be mixed
Google's current specification states that robots.txt only takes effect on the same host, protocol, and port. The rule of www.example.com does not automatically equal shop.example.com.
For large enterprises with multiple subdomain websites, it is especially necessary to check each one individually. Do not think that placing one file in the root domain will cover all services.
08 After going live, verify with actual crawling and indexing reports instead of just looking at the file content
Writing the robots.txt syntax correctly does not guarantee the achievement of business goals. Confirm whether Google can crawl and whether it reads noindex by combining URL Inspection, index reports and server logs.
The most common problem with technical SEO is that the configuration logic seems correct but fails to verify the actual behavior of search engines.
09 The most common error in the test environment is forgetting to remove noindex after going live
Many teams will uniformly add noindex in the pre-release environment, which is a reasonable practice. However, if there is no automated check after copying to the official environment, the entire site may remain unindexed. Conversely, merely disallowing a test site in the robots.txt file does not mean that the page will never appear in search results.
The release process can add environment-level checks: key templates in the production domain are not allowed to have noindex, while the test domain must be subject to access control or explicitly prohibited from indexing. Writing rules into the deployment process is more reliable than relying on manual memory.
10 Crawling budget is not a priority issue that all websites need to optimize
Small and medium-sized enterprise websites often worry about the "crawling budget" immediately upon seeing a large number of parameter URLs, but the real priorities are usually index quality, internal links, and duplicate page management. Only large-scale sites that are frequently updated or have a vast number of URLs are more likely to see their crawling efficiency become a significant bottleneck.
Therefore, the goal of robots.txt should not be to "block Googlebot as much as possible", but to ensure that important pages can be crawled, low-value unlimited space does not get out of control, and at the same time retain the opportunity for search engines to see necessary indexing instructions.
Frequently Asked Questions
Can "noindex" be written in robots.txt?
Google does not support using noindex as a robots.txt directive. meta robots or HTTP Headers need to be used.
Why can the page still be found after disallowing?
Because the URL may be discovered through external links, etc., even though the content has not been crawled.
Is it safer to Disallow and not index at the same time?
Not necessarily. Disallow may prevent crawlers from reading noindex. True access control should be used for sensitive content.
How can a test site best prevent being indexed?
Give priority to using authentication or network restrictions, and combine them with environment-level indexing policies.
Can PDF be noindexed?
Non-html resource indexing can be controlled through methods such as HTTP X-Robots-Tag.
| Related Service | Learn More |
|---|---|
| Corporate Website Design Services | View Service Details |
| Project Consultation | Contact JVDS Design Studio |
| Design and Website Development Articles | Read More Related Articles |
 Link copied








