
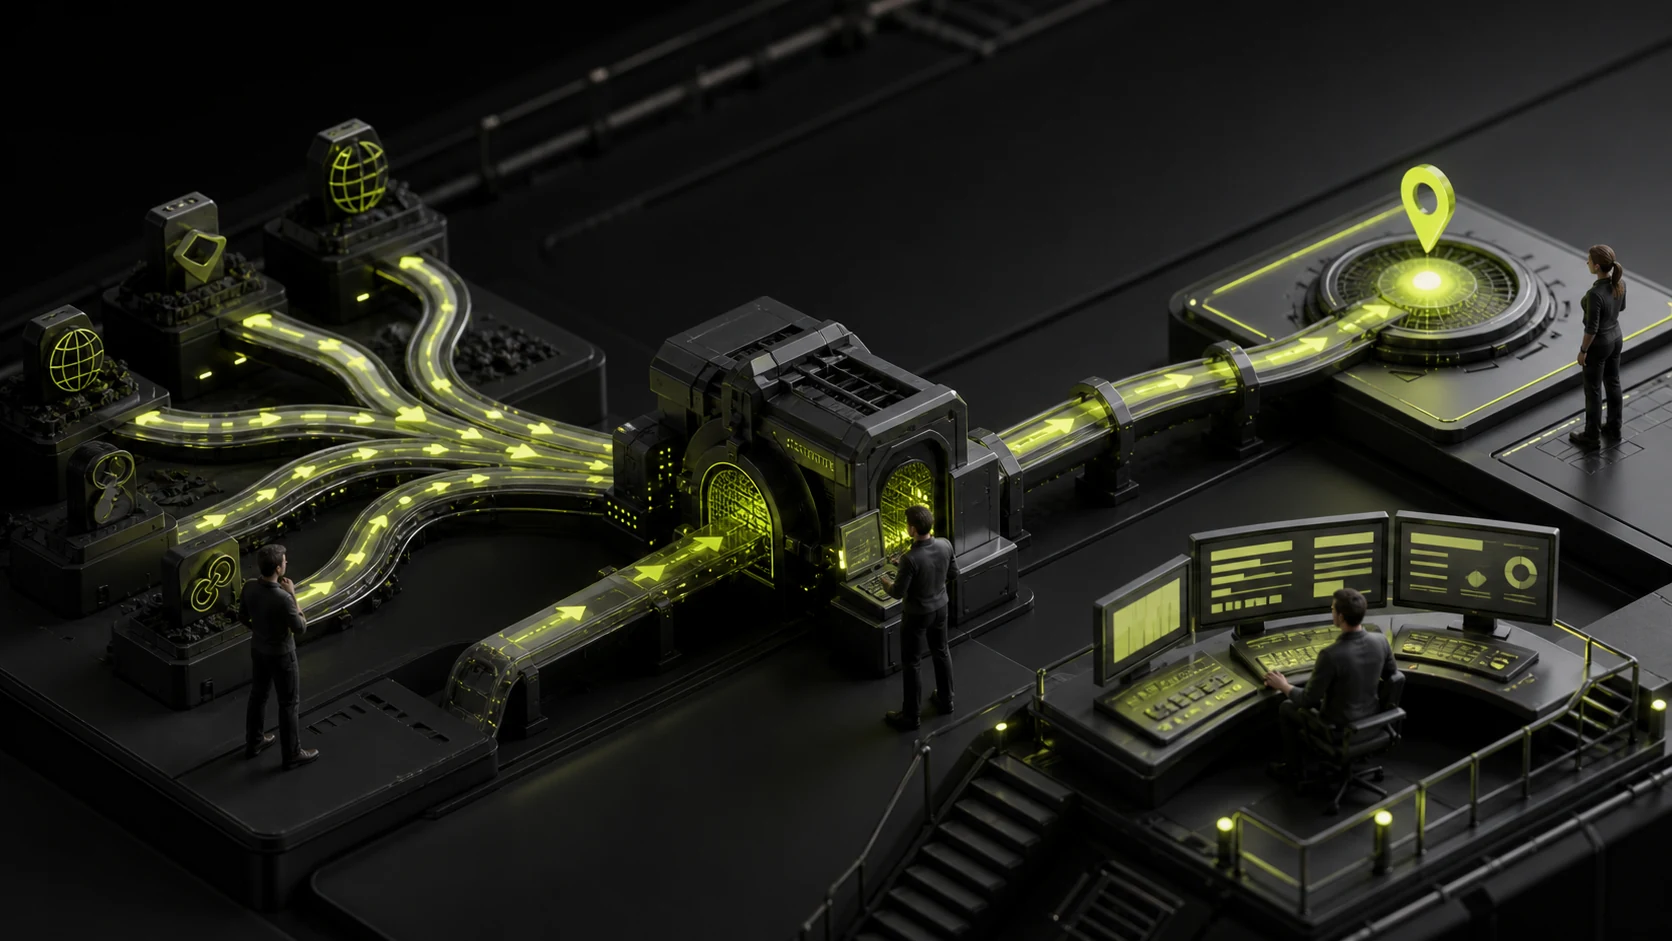
A link may redirect from HTTP to HTTPS, then from non-www to www, and then to a new path. Users can still open it, but crawlers, browsers, and monitoring tools take extra steps.
As the chain grows, targets fail, or rules overlap, it adds latency, wastes crawling, and increases migration risk.
01 Distinguish Necessary Redirects from Incorrect Internal Links
Old backlinks, bookmarks, and historical URLs need redirects. Internal navigation, body links, canonical tags, and sitemaps should point directly to the final URL.
Do not remove valuable 301 redirects merely to make an audit report “zero redirects.”
02 Overlapping Canonicalization Commonly Creates Chains
When HTTP-to-HTTPS, www preference, letter case, trailing slash, language, and path-renaming rules are configured separately, they easily form A→B→C.
Define one URL standard first, then consolidate server or platform configuration.
03 Find Chains with Crawlers, Logs, and URL Inventories Together
A site crawler finds internal links, logs reveal external and historical requests, and sitemaps and analytics add important URLs.
For each chain, record the starting point, every response, the final status, and the source.
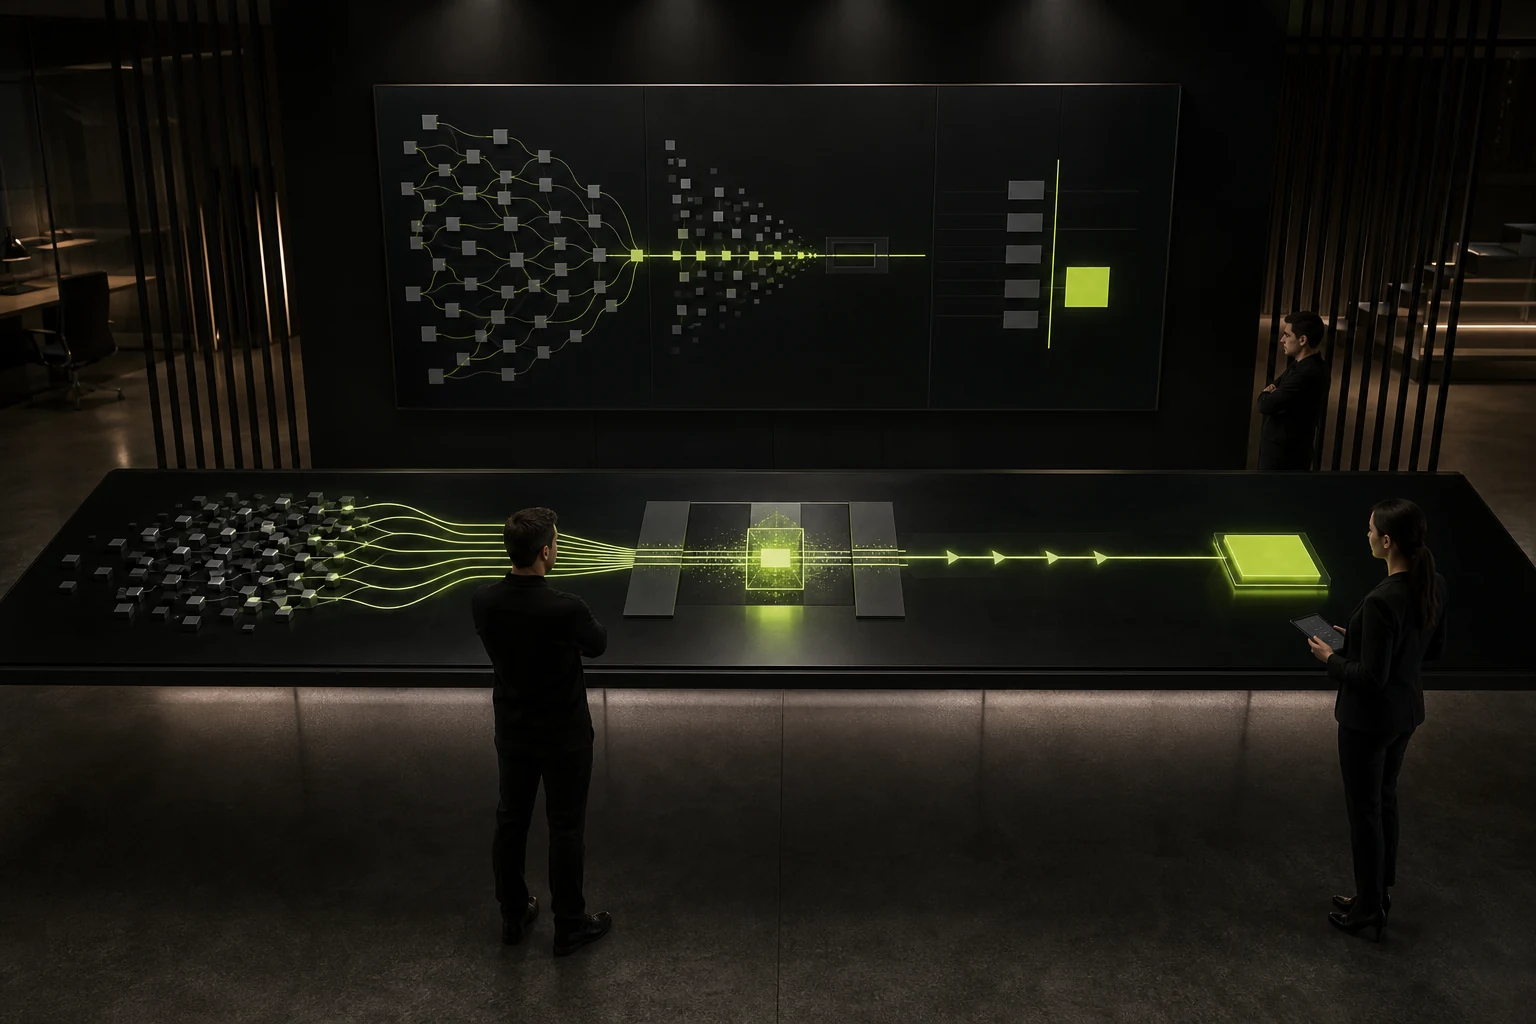
04 Point Directly to the Most Relevant Final Page
Combine intermediate rules into one permanent redirect and update internal links. If old content has no equivalent replacement, do not send everything to the home page.
Irrelevant redirects mislead users and weaken migration quality.
05 Check Loops, Cross-Domain Behavior, and Parameter Errors
A→B→A, HTTP/HTTPS switching, language versions redirecting to each other, and endlessly appended parameters can all create loops.
Test different letter cases, slashes, query parameters, and domain versions.
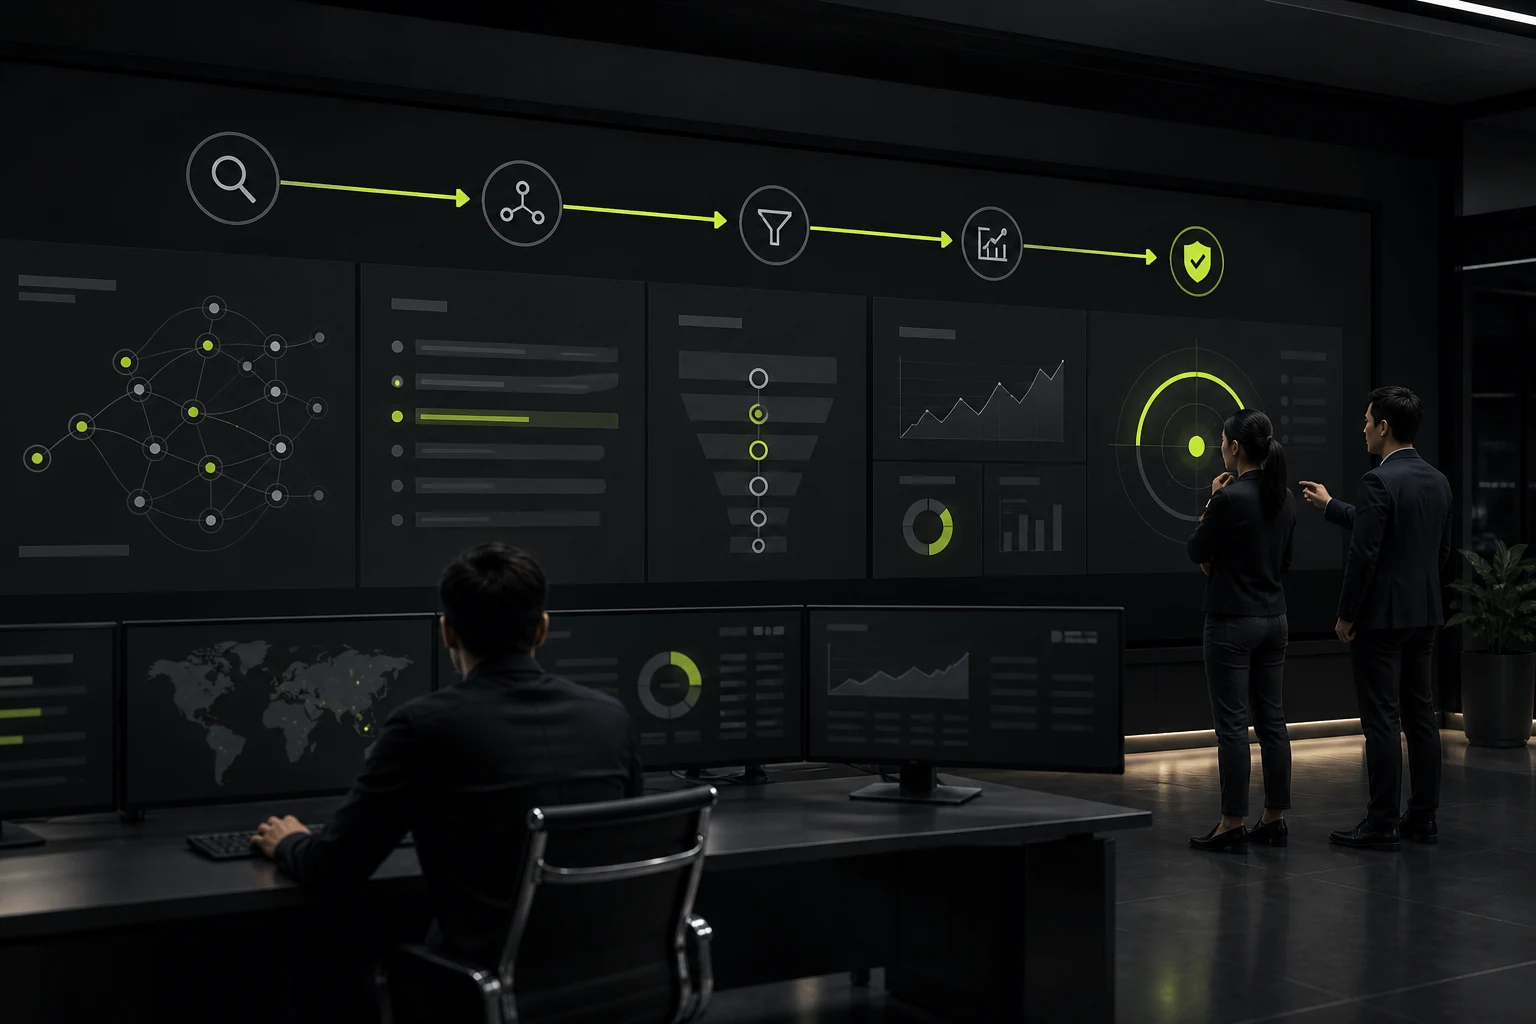
06 Continue Monitoring After Launch
Confirm that final pages return 200, canonical tags agree, and sitemaps contain no redirected URLs, then monitor logs and search-platform errors.
Historical entry points can remain long term, while rules should be reviewed and documented regularly.
Redirect Issue Handling Table
Situation | Correct Handling | Avoid |
|---|---|---|
Old HTTP entry point | One 301 to the canonical HTTPS URL | Redirecting the domain first and path second |
Old article has a new version | 301 to the most relevant new page | Sending everything to the home page |
Internal link points to an old URL | Update directly to the final URL | Relying on redirects as a fallback |
Temporary campaign move | Choose 302 or 307 based on the actual duration | Using temporary rules permanently |
Deleted page has no replacement | Return an appropriate 404 or 410 | Forcing a redirect to an unrelated page |
Frequently Asked Questions
Do redirect chains directly prevent indexing?
Not necessarily, but they increase crawl and maintenance risk. Long or broken chains are more likely to create problems.
Should every 302 become a 301?
No. Genuine temporary redirects can use temporary status codes, while long-term migrations should use permanent redirects.
Should every old page redirect to the home page?
No. Redirect only when the content is relevant; otherwise return an appropriate not-found status.
How many redirects are allowed?
Aim to reach the final page in one step rather than depend on a fixed maximum.
How can future chains be prevented?
Maintain a URL registry, centralize canonicalization configuration, and update a mapping table before every redesign.
Service | View |
|---|---|
Related Services | |
Related Reading | View Service Details |
Design Case Studies | |
Project Consultation |
 Link copied








