Imported Data Duplicates Existing Records: Should It Be Skipped, Overwritten, or Merged?
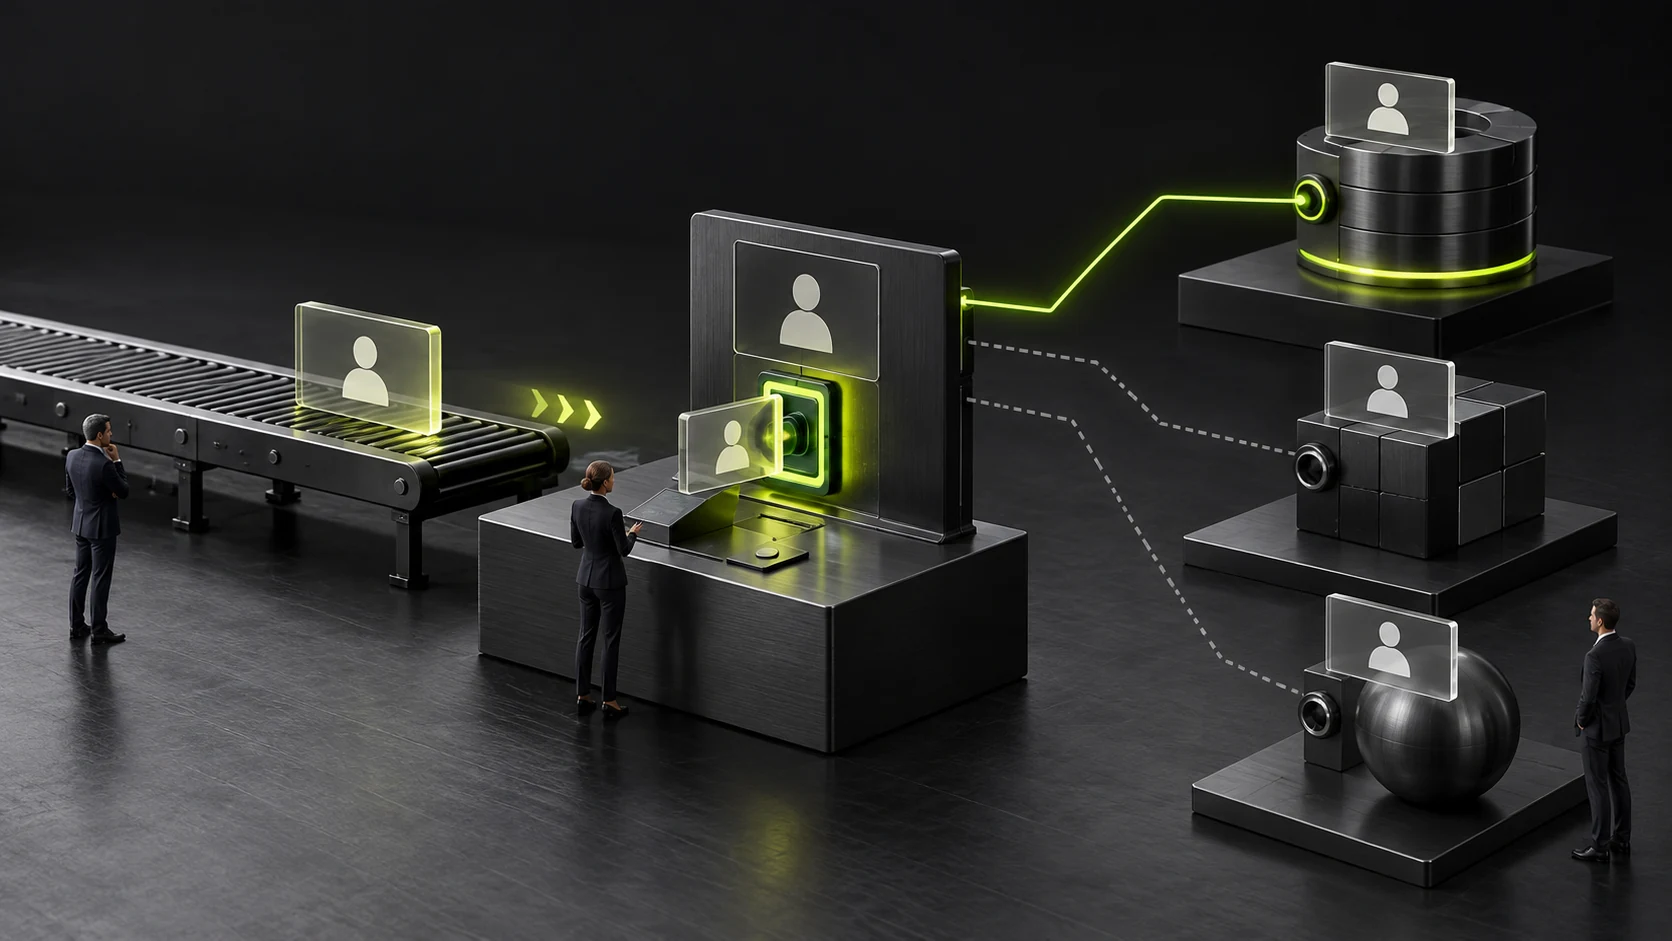
Duplicate import handling first asks why two records are considered the same object, before choosing to skip, overwrite, or merge. Equal names may identify different objects; different names may reflect renaming. Without clear identity, even detailed confirmations cannot prevent editing the wrong record.
Show matching rules and key differences before writes. Users need to identify file-to-site matches, changed and retained values, and traceable outcomes. Imports intended only for creation should not silently treat duplicates as updates.
Duplicate Evidence Should Match Business Identity, Not Only Display Names
Business owners first confirm the object each record represents and stable identifying information. Product codes, business numbers, or confirmed combinations may work according to real data. Do not impose one name or phone-number rule on every object.
Confirm format meanings in matching fields. Whitespace, case, separators, or leading characters may affect identity and need rules. Do not standardize arbitrarily to reduce duplicates or create new records from unexplained differences in apparently identical displays.
External identifiers may be unique only within their own sources. Matching numbers from two sources need not identify one object. Explain relationships between sources and site identities instead of treating an external number as universally unique.
Check duplicates inside a file separately from matches with existing records. Two conflicting rows for one object can repeatedly overwrite during import if only site existence is checked. Preflight should cover the whole pending file and explain how conflicts reach decisions.
Version changed matching rules with scope too. Switching identifying combinations may alter object relationships when retrying old files. Check continuity of historical handling before adopting rules, preventing successful records from becoming newly unmatched data.
Use awaiting-verification status when identity is uncertain rather than forcing a similar match. Reviewers receive necessary identifiers and sources for confirmation under real responsibilities. Ambiguous matching is unsuitable for default unpredictable updates.
Show Old Records, New Content, and Fields That Will Change
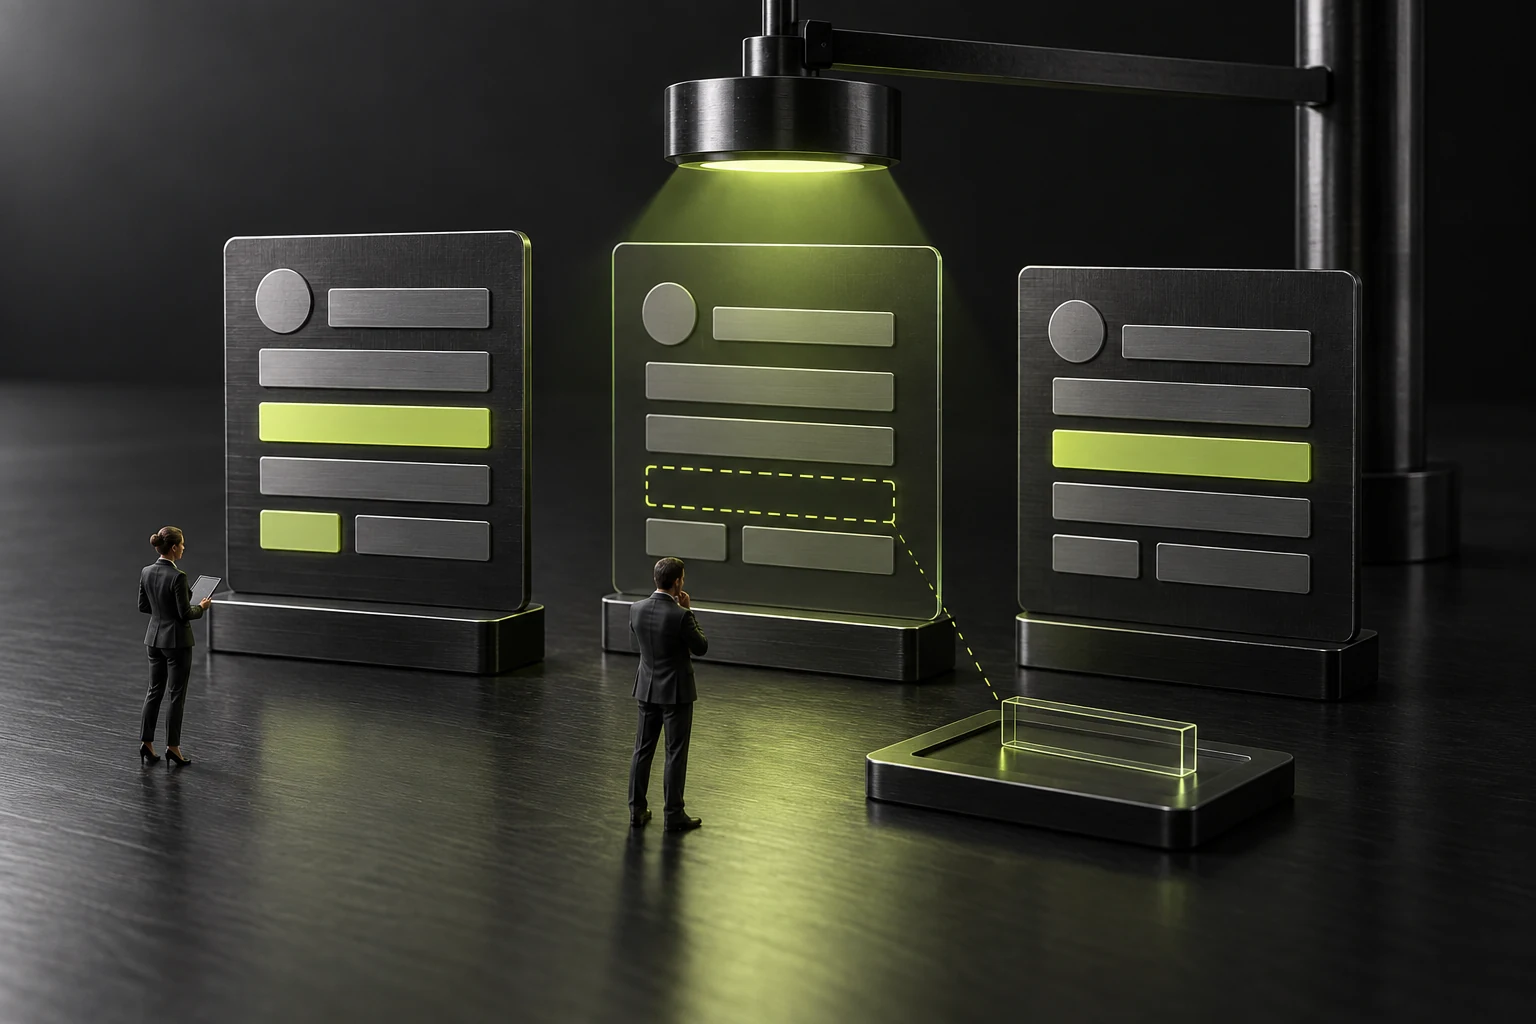
Preflight summaries can state counts of creations, duplicates, conflicts, and unidentified items, then offer object details. Matching details need file locations, site identities, matching evidence, and key differences beyond “row ten duplicated.”
When several site objects match one input, a single result is insufficient. Explain ambiguous identity and require checking rather than choosing the first. Necessary information helps owners decide, but default overwrites would let vague rules change unpredictable records. See Why are SaaS backend tables getting more and more difficult to use as they are made? The real problem with the data table is not "too much information", but that the tasks have no priority for related checks.
Difference views prioritize decisions. Identical duplicates can briefly state no changes needed; differing values show old and new values and candidate effects. Layer long text or attachments instead of displaying every complete record and hiding key changes.
Define blanks separately. File blanks may mean no new information or instructions to clear existing values. These differ and cannot be guessed by tools. Field rules and update previews should show the adopted meaning and clearing effects.
Site workflows may maintain review states, owners, or history that external files cannot overwrite. Distinguish permitted updates, retained values, and separately handled fields by real rules and permissions so whole-row replacement does not alter business relationships accidentally.
A recently uploaded file may come from an old system snapshot. Check data formation times and applicability rather than calling upload time freshness. Handling should reflect real material relationships instead of an unconfirmed last-uploader-wins policy.
Each of the Three Actions Serves a Different Task
Skipping suits unchanged existing objects or creation-only tasks. It preserves old records without adopting new file values. Explain counts and reasons; skipped items cannot be called successfully updated and suggest new content took effect.
Overwriting suits confirmed replacement of permitted fields from new sources. State whole-record or specific-field scope, blank handling, and related effects. “Overwrite duplicates” alone does not tell users what changes.
Merging needs explainable combinations, such as filling missing information or combining allowed tags. It is not independent judgment of better values. Conflicting key fields still need adopted rules or manual confirmation rather than “smart merging” concealing unknown decisions.
A batch may handle different objects differently within explainable options. If rules require fresh guessing for every row, resolve materials or split batches first. Freedom alone does not ensure reliability; clear defaults and effects matter more.
Creation defaults should follow creation purposes. Without explicit update authorization, preflight refusal or skipping better respects creation boundaries; updates require separately confirmed approaches. Business and implementation jointly choose strategy rather than treating arbitrary overwrites as natural import behavior.
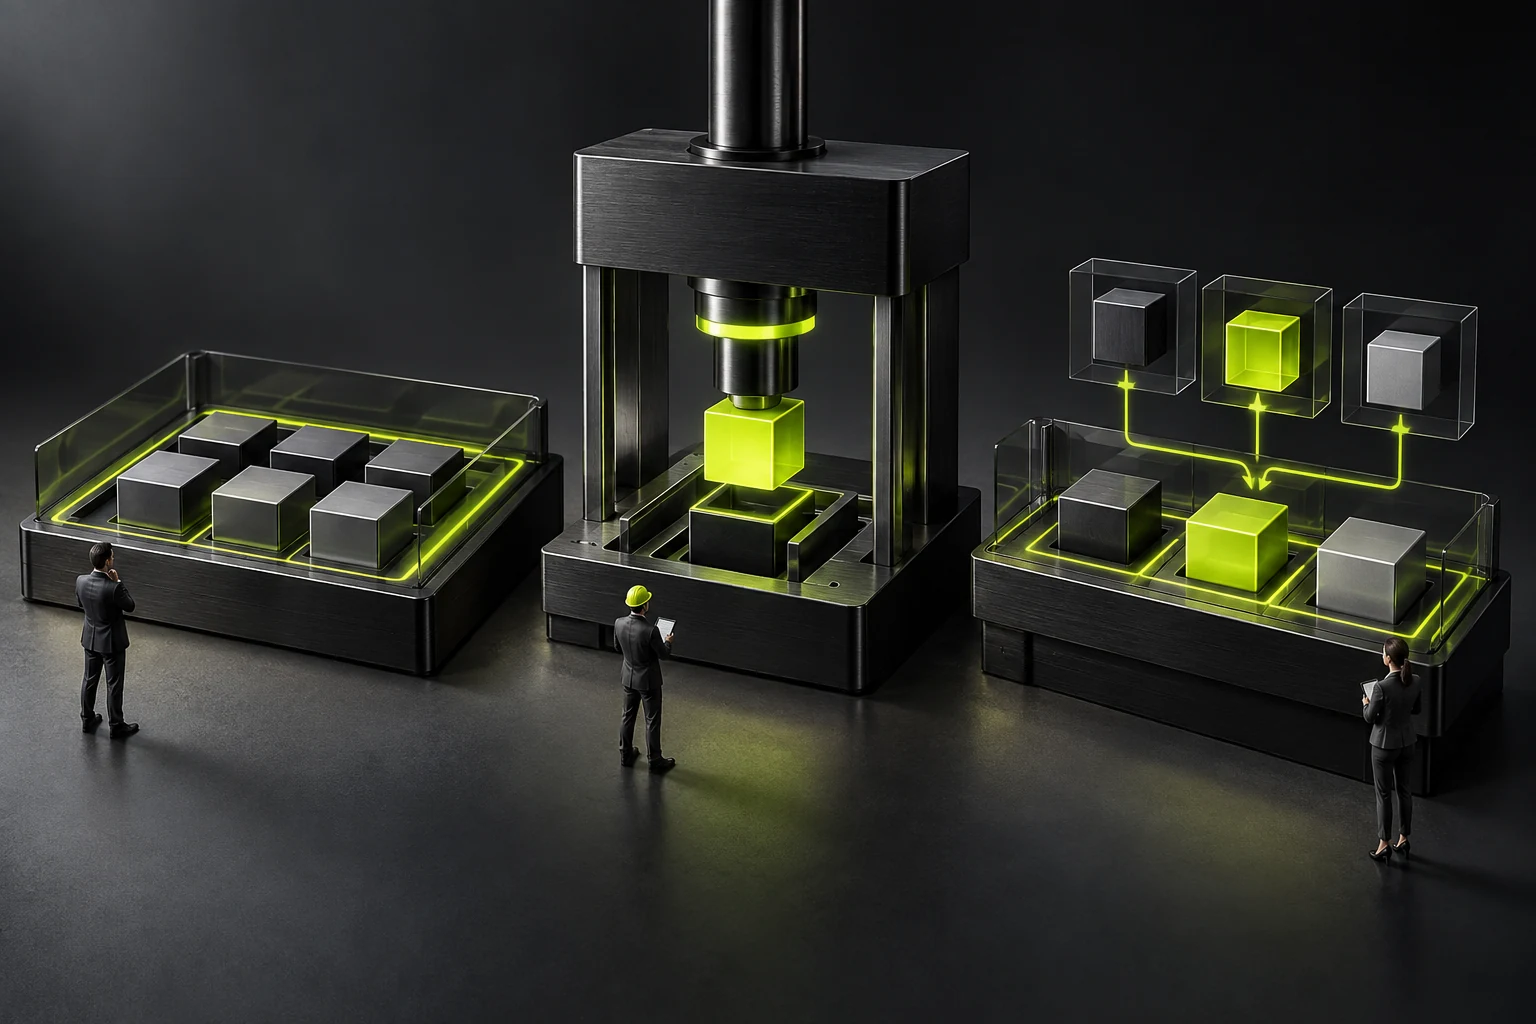
Record Actual Results After Confirming the Approach
Confirmation should correspond to a defined file, rules, and preflight. Changed files, matching conditions, or approaches require checks according to capabilities instead of reusing old summaries. Approval concerns actual current scope, not a similar earlier file.
Existing records may also change between preflight and execution. Apply confirmed conflict rules to actual writes and explain deviations. Expected success counts cannot be treated as execution counts; final records determine results.
Details can include file rows or identities, site objects, actual actions, changed fields, and failure reasons. Preserve source and batch relationships for later checking. “Import successful” alone cannot identify skipped, updated, or newly created duplicates.
For partial success, list success, skipping, conflicts, and failures separately with continuing scope. Retrying corrected data must avoid recreating successful objects. Implementation confirms duplicate prevention and interfaces explain the identities and rules reused.
Without undo, do not guarantee restoration. Before-and-after relationships can support checks, but actual data and later workflows determine recovery. High-impact overwrites need adequate pre-write confirmation rather than a default assumption of undoing mistakes.
Verify Rules With Small Recognizable Samples Instead of Experimenting on Production Data
Prepare same-name/different-identity, different-name/same-identity, internal-duplicate, blank-conflict, and related-field-change samples. State expected objects and actions for each using constructed data in controlled environments.
Check preflight explanations first, then execute a confirmed small batch and inspect records. Detecting duplicates does not prove handling accuracy; final objects, fields, and details must correspond. Small tests should still cover real rule boundaries.
Retry samples to ensure successful objects are not recreated through invalid retry identities. Change one pending item and verify only intended scope changes. One successful import tests normal paths; retries check sustainable duplicate handling.
Have business reviewers choose approaches from previews, then implementers check effects accordingly. If overwrite means different things to each, resolve terminology and fields before formal batches. Clear decision language reduces later disputes.
Completion means business-based identity, visible internal and external conflicts, explicit action effects, traceable results and sources, and no unsupported recreation on retries. Duplicate handling should explain objects and changes rather than give one button control over all data. See How to Design Data Import: Templates, Validation, Progress, and Failure Recovery for related checks.
Frequently Asked Questions
Can Identical Names Automatically Count as Duplicates?
Only if names are confirmed unique identifiers. Most business data needs stable identities or combinations; matching displays alone cannot merge different objects.
Why Does Skipping Not Adopt New File Information?
Skipping normally preserves old records. Adopting new values requires confirmed update tasks and permitted fields before choosing an approach. Skipping does not mean synchronized.
Is Merging Always Safer Than Overwriting?
No. Unclear merging can alter important fields too. Define identical, conflicting, and blank handling before judging suitability instead of inferring risk from names.
Can We Import Only the First of Two Duplicate Rows?
Check equality and business rules. Conflicting values need preflight and clear evidence; first-row position does not prove correctness.
How Can Re-uploading After Failure Avoid Recreating Successful Items?
Identify them through confirmed identities and batch results, retain success details, and retry pending scope. Verify capabilities in implementation rather than relying only on “do not upload twice.”
 Link copied